Building a multi-source hiring intelligence engine with canonical normalization and change tracking
A Python acquisition layer that converts heterogeneous applicant-tracking systems into dependable, comparable job-market signals.
| STATUS | Beta · Source reviewed · Selected tests passing |
|---|---|
| TEAM | Solo engineering project |
| DEMO | Fixture-based technical demo planned |
| SOURCE | Private repository |
Executive Summary
Every applicant-tracking system represents the same idea — a job posting — differently: different APIs, different HTML, different pagination, different field names for the same concept. This engine puts ten of them behind a shared adapter interface, converts everything into one canonical job model, and computes the delta between snapshots rather than re-ingesting the same postings as new data every run.
Context
Structured as a proper Python package — Python 3.11+, database schemas, orchestration scripts, observability hooks — with dedicated modules for rate limiting, proxy health, normalization, revision history and hiring-velocity scoring, aimed at recurring monitoring rather than a one-off export. It is the acquisition core that also powers the job-market side of the larger Elevya Signal Intelligence platform elsewhere in this portfolio, built first here as a standalone, reusable package.
My role and ownership
- Adapter and registry architecture
- Normalization and delta processing
- Rate limiting, retries and proxy-health controls
- PostgreSQL schemas and revision history
- Automated tests for core logic and sources
Personal contribution
Adapters, registry, canonical model, state comparison, revisions, network controls and tests.
Problem
A title with a requisition code baked in, a location string that mixes city and remote-work signals in no consistent order, a salary range written as free text, a contract type spelled four different ways across four platforms — none of that is usable for comparison until it's normalized. And without snapshot-to-snapshot comparison, "new data" is really just the same postings re-ingested on every run.
BEFORE
- One-off source-specific scripts
- Different field names and types per ATS
- Repeated processing when boards have not changed
- No durable record of added, changed or removed jobs
- No company-level hiring momentum signal
AFTER
- Adapter registry with source-specific clients
- Canonical title, location, contract, salary and function fields
- Conditional fetch and rate-limit controls where supported
- Delta and revision layers for lifecycle tracking
- High-Velocity Indicator for acceleration classification
Meaningful result: Ten ATS integrations converge on one canonical job and change model.
Solution
Ten source adapters — Greenhouse, Lever, Ashby, Workable, Personio, BambooHR, Recruitee, SmartRecruiters, Teamtailor and France Travail — sit behind one registry and shared orchestration, so adding an eleventh platform means writing one adapter, not touching the pipeline that runs all ten. Every record, regardless of source, lands in the same canonical schema.
A delta module compares each new snapshot against the last known state per source, so only genuine changes generate a revision record instead of re-writing everything every run. A hiring-velocity module turns the resulting change history into a company-level acceleration signal — the piece that makes ten normalized feeds worth more than ten spreadsheets, because it answers "who's hiring faster than last month," not just "who's hiring." The pipeline in sequence:
Engineering
The package targets Python 3.11+ and uses asyncio, httpx, psycopg and Selectolax. The adapter interface is strict enough that the orchestrator never needs to know which platform it's talking to, at the cost of upfront design time — a cost that pays back every time a new ATS gets added, since the tenth adapter took a fraction of the effort the first one did.
Thin adapters, shared policy
Platform-specific parsing stays isolated while retries, rate limits, metrics and database behavior improve once for the whole engine.
Normalize before downstream use
A canonical job record converts inconsistent titles, locations, contracts and salaries into fields that support analytics.
Track revisions, not only current rows
Delta processing distinguishes new, changed and closed jobs and preserves evidence for hiring momentum.
Test contracts and edge cases
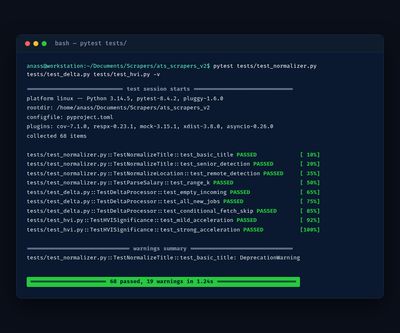
The repository includes tests for infrastructure and adapters; the supplied capture shows 68 passing tests with 19 warnings.
Visual Proof
Outcome
Ten adapter source files, 24 test modules covering infrastructure and platform clients, and PostgreSQL schemas for core records, revisions and cache with optimized indexes — this is the acquisition layer that made the larger Signal Intelligence platform possible to build in the time it took, because the hardest normalization problem was already solved and tested here first.
Verified evidence
- 10 adapter source files identified
- 24 test modules covering infrastructure and platform clients
- Captured selected run: 68 passed, 19 warnings in 1.24 seconds
- PostgreSQL schemas for core records, revisions, cache and optimized indexes
- CLI scripts for sweeps, exports, HVI backfill and classifier training
Current limitations
- No live multi-platform sweep was captured for this portfolio package.
- The screenshot proves selected tests, not every production integration or credential path.
- An optimization percentage in source documentation lacks a benchmark artifact and is not repeated here.
- Warnings remain in the captured suite and should be removed or explicitly accepted.
- A public demo should use fixtures or cached responses.
| STATUS | Beta · Source reviewed · Selected tests passing |
|---|---|
| TEAM | Solo engineering project |
| DEMO | Fixture-based technical demo planned |
| SOURCE | Private repository |
WHY THIS PROJECT MATTERS
Ten ATS integrations converge on one canonical job and change model.
This case study is designed to be inspectable: strong claims are connected to screenshots, source evidence or explicitly stated limitations.